
When a crisis hits, the systems you ignored become the story.
The winter storm that swept across the United States in December 2022 made headlines. The operational collapse that followed made history.
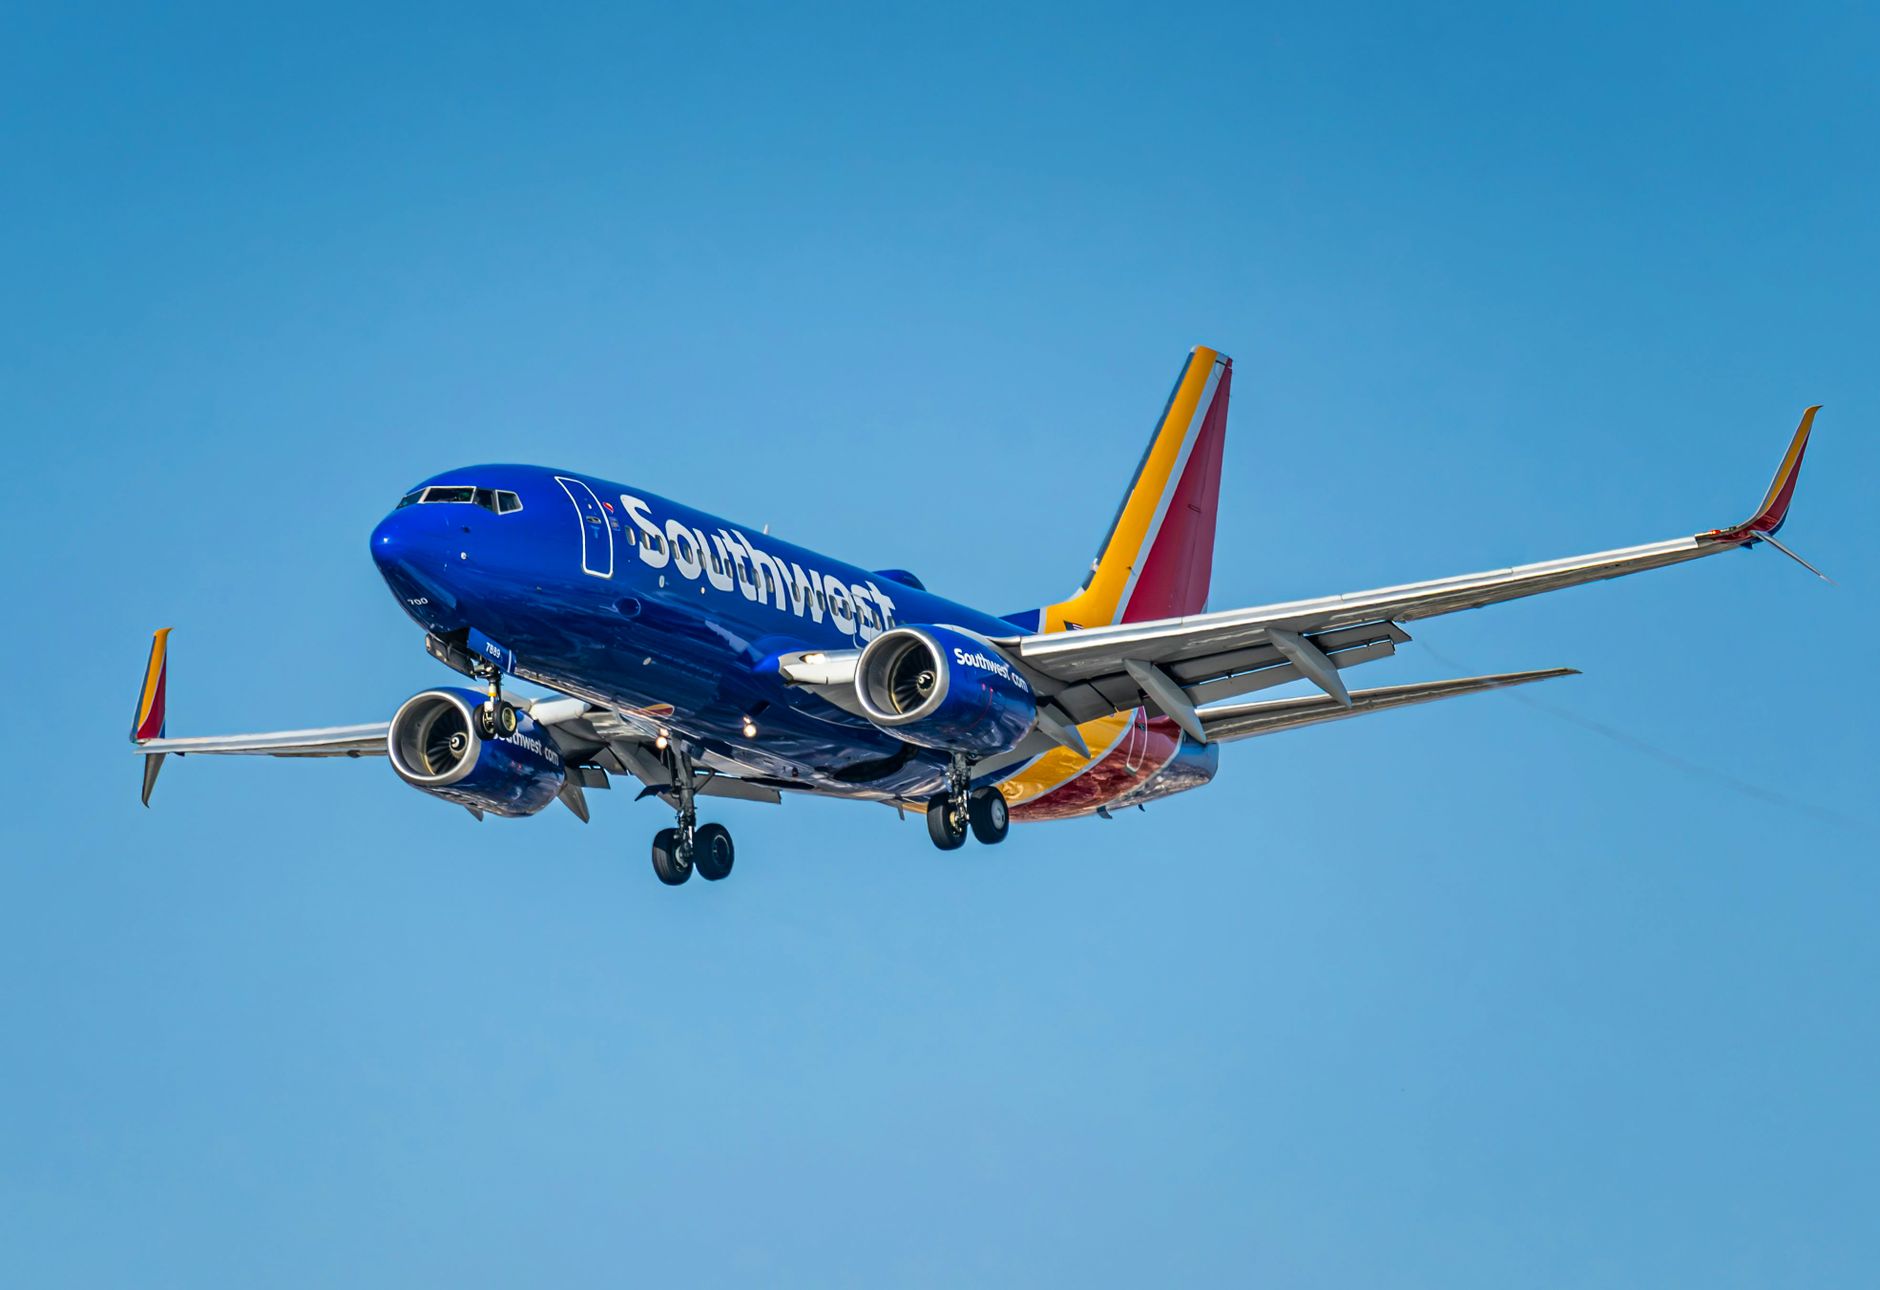
For many travelers, the event appeared straightforward enough. Bad weather grounded flights. Airlines struggled. Holiday travel became chaotic. Yet one airline experienced a level of disruption far beyond its competitors. While other carriers gradually recovered, Southwest Airlines entered a downward spiral that resulted in roughly 16,700 canceled flights, stranded passengers across the country, overwhelmed employees, and a public relations crisis that lingered long after the snow stopped falling.
The storm may have been the trigger, but it was not the root cause.
According to Peng and colleagues, the crisis revealed fundamental weaknesses in the airline’s scheduling and operational systems that prevented recovery once disruptions reached a critical scale. What looked like a weather problem was actually a technology problem wearing a weather-themed disguise. When the systems responsible for tracking crews and aircraft became overwhelmed, employees increasingly relied on manual processes to keep operations moving. As Witman and coauthors describe, the resulting breakdown exposed years of accumulated technical debt, operational complexity, and organizational risk.
For project managers, technology leaders, and executives, the Southwest incident offers a valuable lesson. Major failures rarely emerge from a single catastrophic event. More often, they are the result of small compromises, deferred upgrades, temporary workarounds, and ambitious assumptions accumulating over time until an external event exposes the cracks.
In many ways, the Southwest meltdown serves as a reminder that technology projects do not fail only when systems stop working. Sometimes they fail when systems continue working just well enough to avoid scrutiny.
The discussion around failed projects often focuses on budgets, schedules, or missed requirements. Those factors certainly matter, but one of the most important project management tools frequently receives less attention than it deserves: the scope statement.
At first glance, a scope statement can appear deceptively simple. It defines what a project intends to accomplish, what it will deliver, how success will be measured, and what falls outside the project’s boundaries. Yet those seemingly straightforward details often determine whether an organization builds a resilient solution or merely creates a more sophisticated version of an existing problem.
Had Southwest approached modernization efforts through a scope statement centered on operational resilience rather than incremental improvement, the outcome might have been very different.
The most important component would have been a clearly defined objective. Too often, organizations establish objectives around efficiency, cost reduction, or routine operational performance. Those goals are understandable, but they can create blind spots. Systems rarely earn their keep during normal operations. Their true value becomes apparent during moments of extraordinary stress.
A stronger objective would have focused explicitly on disruption recovery and large-scale operational resilience. Instead of asking whether systems could support daily scheduling activities, project leaders could have asked whether those same systems could continue functioning during network-wide disruptions affecting thousands of flights simultaneously. That distinction may seem subtle, but it changes everything about how requirements are defined, tested, and implemented.
Science fiction fans may recognize a familiar pattern. Starfleet vessels rarely encounter trouble while cruising peacefully between missions. The real test comes when the ship is under attack, systems are failing, and someone inevitably announces that the warp core is unstable. Designing only for ideal conditions creates the illusion of reliability. Designing for failure creates actual resilience.
Deliverables represent another area where project scope can determine long-term success.
Organizations frequently approach modernization as a series of isolated upgrades. One system gets patched. Another receives new hardware. A third gains a handful of new features. On paper, progress appears measurable. In practice, underlying dependencies remain fragmented.
The Southwest crisis highlighted the dangers of this approach. According to Witman and colleagues, operational teams became increasingly dependent on manual interventions as automated systems struggled to coordinate crews and aircraft. Those workarounds may have helped address individual problems over the years, but they also masked larger structural weaknesses.
An effective scope statement would have identified integrated automation as a required deliverable rather than an optional enhancement. Instead of focusing on individual software components, project teams could have been tasked with delivering a unified scheduling ecosystem capable of maintaining real-time awareness across operations. Deliverables would include automated crew assignment, network-wide visibility, dynamic recovery planning, and seamless communication between operational systems.
In other words, the project would focus on solving the problem rather than updating the tools associated with the problem.
Milestones represent another frequently overlooked element of project scope.
Many organizations establish milestones based on implementation activities. A system is installed. A feature is released. A database is migrated. While those achievements matter, they do not necessarily demonstrate readiness.
A more strategic approach ties milestones to outcomes rather than activities.
For a project focused on operational resilience, meaningful milestones would include simulation exercises, stress testing, disaster recovery validation, and phased deployment under increasingly demanding conditions. Before declaring success, project leaders would need evidence that systems could perform under the exact circumstances most likely to challenge them.
One of the most striking aspects of the Southwest incident is that the affected systems apparently functioned adequately under normal conditions. The breakdown occurred when operational complexity exceeded design assumptions. That distinction highlights why milestone validation matters so much. A system that works during routine operations may still fail catastrophically during a crisis.
This is where many organizations discover that their testing strategy resembles studying for an exam by reviewing only the easiest questions.
Technical requirements play an equally critical role.
Every project includes requirements, but not all requirements are created equal. Functional requirements describe what a system should do. Resilience requirements describe what a system must continue doing when everything goes wrong.
For an airline scheduling platform, technical requirements should extend well beyond basic functionality. Scalability, redundancy, fault tolerance, recovery speed, and real-time processing capabilities become essential design considerations. The system must not only process information accurately but also maintain performance as operational demands increase dramatically.
The challenge is that resilience requirements often compete with budget constraints and delivery timelines. Features are visible. Reliability is frequently invisible until it disappears.
As a result, organizations sometimes prioritize capabilities that users can see while postponing investments in infrastructure that users rarely notice. The Southwest crisis demonstrated the danger of that tradeoff. Customers may never think about backend scheduling systems during a normal flight. They think about them very quickly when they cannot get home for the holidays.
Another valuable component of project scope involves limits and exclusions.
At first, this may seem counterintuitive. Why spend time documenting what a system will not do?
The answer is simple. Assumptions are dangerous.
Clearly defined exclusions force project teams to acknowledge constraints and identify potential gaps. If a scheduling system cannot support a particular disruption scenario, leadership should know that before a crisis occurs rather than during one.
Exclusions create opportunities for risk discussions that might otherwise never happen. They encourage organizations to ask uncomfortable questions about operational vulnerabilities. They also prevent stakeholders from assuming capabilities that were never actually delivered.
In many failed projects, the problem is not that requirements were ignored. The problem is that assumptions were never challenged.
Perhaps the most important element of all is regular stakeholder review.
Technology teams often understand systems. Operations teams understand reality.
Successful projects require both perspectives.
Regular reviews involving frontline employees, operational leaders, technical architects, and business stakeholders create opportunities to identify emerging risks before they become systemic failures. Employees who interact with systems daily often recognize limitations long before executives see them in reports.
According to Witman and colleagues, Southwest employees increasingly relied on manual processes during operational disruptions. That detail is particularly significant because workarounds frequently serve as warning signs. Every spreadsheet created outside a system, every manual process added to compensate for missing functionality, and every unofficial procedure developed by frontline staff represents valuable feedback about where technology is falling short.
When organizations fail to listen to those signals, they risk normalizing inefficiency and embedding fragility into critical operations.
The Southwest meltdown ultimately became a case study in much more than airline operations. It illustrated how technical debt accumulates, how operational risk evolves, and how project decisions made years earlier can shape outcomes during a crisis.
Most organizations will never manage a national airline network. They will, however, face their own versions of unexpected disruption. Market shifts, cybersecurity incidents, infrastructure failures, supply chain challenges, and operational emergencies all test whether technology investments were designed for resilience or merely convenience.
That is why scope statements matter.
They are not administrative paperwork. They are strategic documents that establish expectations, define success, expose assumptions, and guide decision-making throughout a project’s lifecycle.
When written thoughtfully, they help organizations build systems capable of handling both ordinary operations and extraordinary circumstances. When treated as a formality, they can create a false sense of confidence that lasts right up until reality arrives.
The storm that hit Southwest in 2022 was unavoidable. The technology challenges that followed were not.